Table of Contents
1. Hangfire was the right starting point
Hangfire let us ship the first version quickly. We got durable jobs, retries, schedules and a dashboard without building queue infrastructure ourselves. While we were still learning how the Allegro integration behaved, it was the right tradeoff.
Over time, the process stabilized. We knew what success meant, which failures should be retried and how to process the same offer safely more than once. That gave us enough information to design a queue around the actual workload.
2. What changed at scale
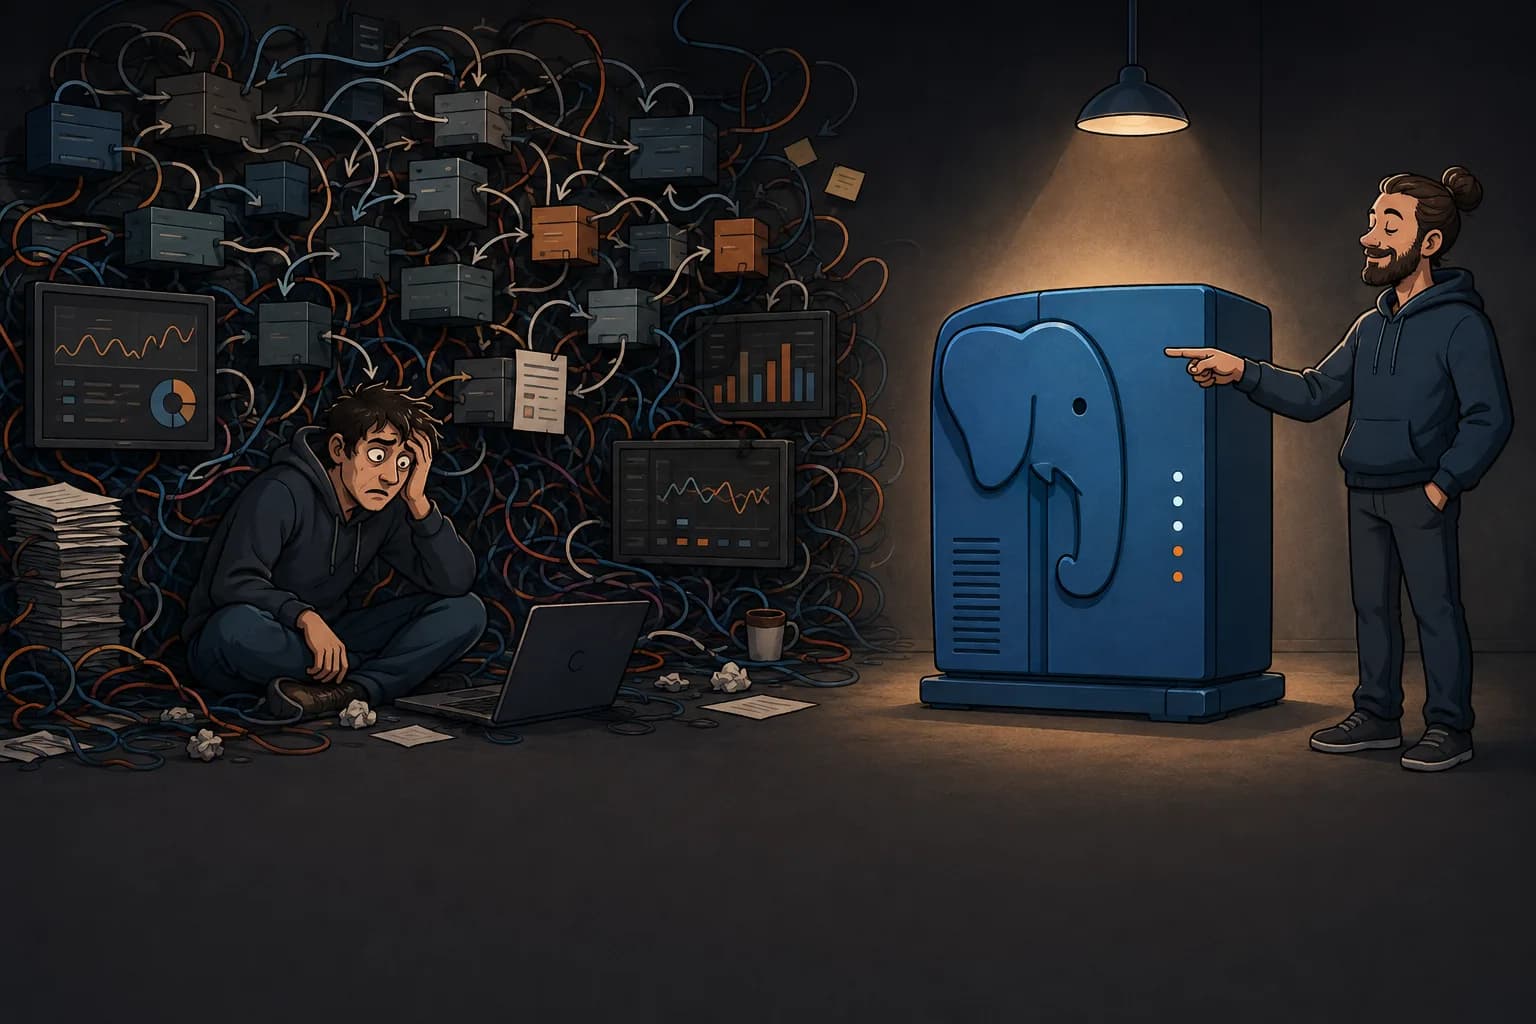
The job-per-offer model created thousands of durable Hangfire records during a single synchronization. For the largest account, the workload was close to one million offers. Every job had to be stored, scheduled and eventually cleaned up before the actual API work even began.
Throughput was still constrained by Allegro and other integrations. One million queued jobs could not produce one million safe parallel requests. It increased scheduler overhead, made queue operations harder and mixed bulk synchronization with shorter jobs.
Just use Postgres
3. Why we moved the queue to PostgreSQL
Once the process was stable, we moved the bulk workload into a PostgreSQL table. Each offer that needs refreshing has one row. Another event for the same offer updates the existing work instead of creating another job.
Hosted .NET services claim small batches, call the integration and save the result. Failed work becomes available again later. PostgreSQL stores the state next to the business data and uses the transactions, backups and monitoring already present in the system.
One offer, one work row
Repeated events do not inflate the queue.
Small batches
A worker claims only the work it can handle now.
State in the database
Backlog, retries and failures are visible through ordinary queries and metrics.
4. Controlling integration concurrency
The number of pending rows does not control the number of parallel requests. We set an explicit concurrency limit for calls to Allegro and other integrations. The backlog can be large while the application performs only as much work as the external APIs and our infrastructure can safely handle.
PostgreSQL also prevents multiple processes from handling work for the same account at once. That is enough at the current scale. A more advanced fair scheduler would make sense only if large accounts began to delay everyone else.
5. When this approach makes sense
The process is proven
You understand its states, retries and completion rules.
The work has a natural key
Multiple signals can update one row instead of appending jobs.
An external API limits throughput
A larger queue will not increase safe request capacity.
The jobs are numerous and similar
You are processing data at scale rather than thousands of distinct workflows.
Hangfire still handles schedules, notifications and operator-triggered tasks in SellersKit. PostgreSQL owns the repetitive offer processing. Today we start with a proven job system, measure it in production, then move stable bulk work closer to the data when scale starts creating operational cost.
Is Hangfire starting to limit your system?
We help teams separate workflows from bulk data processing and move their busiest paths to PostgreSQL without losing business state.